10Web
Web Development Website Builders
Learn more
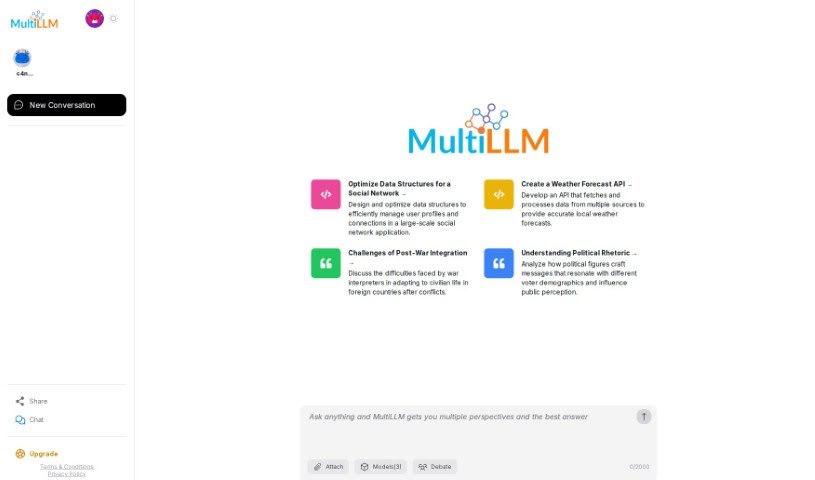
Verifai's MultiLLM is an open-source Python framework that runs multiple LLMs in parallel and ranks their outputs to surface the most accurate answers.
VerifAI’s MultiLLM is an open-source Python framework that runs multiple language models (LLMs) in parallel, compares their outputs, and ranks the results to identify the most accurate answers. It is built primarily for comparing code generated by popular LLMs such as GPT3, GPT5, and Google-Bard. You can add new LLMs and customize how outputs are ranked. Cross-checking results across models reduces the risk of relying on incorrect information from a single LLM. The framework is available on GitHub.
Verifai is aimed at software developers, data scientists, researchers, academics, and students.
Install the MultiLLM framework from GitHub along with its dependencies. Configure it to run your chosen LLMs in parallel and adjust the ranking functions to evaluate outputs according to your needs. Submit a task — code generation or a general question — and MultiLLM ranks the outputs to surface the most accurate result. The Verifai blog article on MultiLLM covers more detail, and the open-source repository tracks new features and improvements.
Related
Discover more tools in similar categories
Weekly picks of the best AI tools we've researched and added — no spam, unsubscribe anytime.
Join 25,000+ AI enthusiasts. No spam, unsubscribe anytime.