GPTOCR (Productivity)
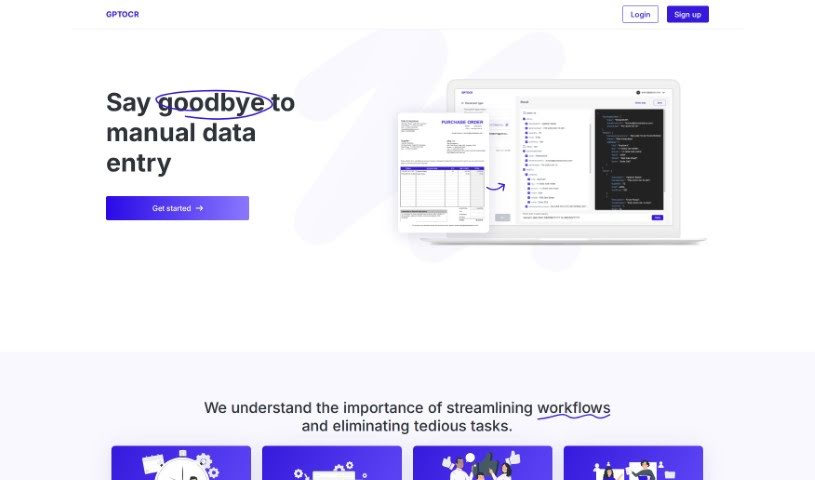
Screenshot of GPTOCR

GPTOCR

GPTOCR extracts data from PDFs into structured JSON using OpenAI's GPT models, automating manual data entry with standardized output.

Screenshot

What is GPTOCR?

GPTOCR uses natural language processing and deep learning to extract data from PDF documents and convert it into structured data, typically JSON format. It automates manual data entry and formatting, reducing errors and giving teams standardized data to work with. It handles scanned, image-based, and plain-text PDFs, regardless of complexity or page count.

Who created GPTOCR?

GPTOCR was created by OpenAI, which uses its GPT models to extract and transform data from PDFs into structured JSON files.

What is GPTOCR used for?

  • Data extraction: Pulls information out of documents automatically.
  • JSON conversion: Transforms documents into structured, machine-readable output.
  • Error reduction: Less manual entry means fewer mistakes and more consistent data.
  • Workflow automation: Streamlines data processing and reduces manual check time.
  • Collaboration: Standardized output helps teams share and work with the same data.
  • Data confidentiality and security: Information is kept safe during processing.
  • Complex documents: Handles unstructured sources, any document layout, and large volumes of data while maintaining data context during extraction.

Who is GPTOCR for?

GPTOCR is particularly useful for finance, healthcare, and research professionals who need to extract structured data from documents.

How to use GPTOCR?

  1. Upload the PDF containing the data you want to extract.
  2. GPTOCR processes the document and organizes the extracted data into JSON format.
  3. Review the structured, machine-friendly output.

Related

Related AI Tools

Discover more tools in similar categories

New tools, in your inbox.

Weekly picks of the best AI tools we've researched and added — no spam, unsubscribe anytime.

Join 25,000+ AI enthusiasts. No spam, unsubscribe anytime.