123RF AI Image Generator
Creative Image Generation
Learn more
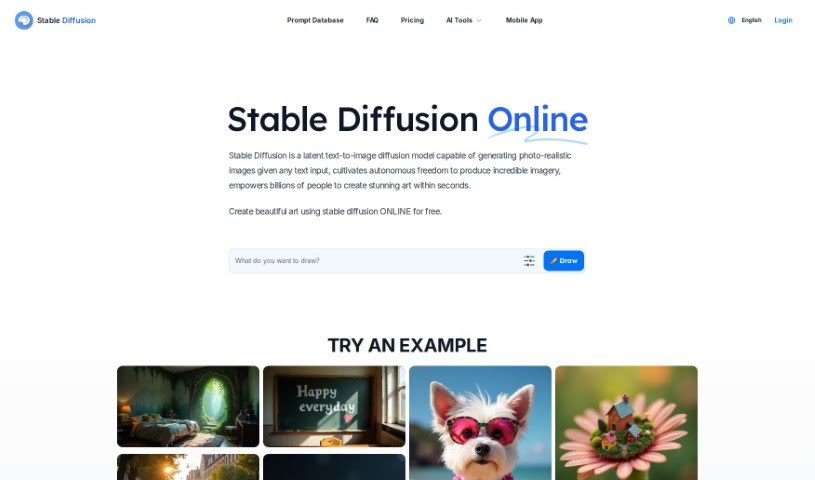
Stable Diffusion is a deep learning model that generates photo-realistic images from text, with inpainting, outpainting, and fine control over style.
Stable Diffusion is a deep learning model that turns text descriptions into high-quality, photo-realistic images. The latest version, Stable Diffusion XL, uses a larger UNet backbone network to produce better images.
The model offers significant control over output: you can guide generation with descriptive text specifying style, shot type, or pre-set looks. Beyond creating new images, it can modify existing ones — techniques like inpainting and outpainting let you add, replace, or extend parts of an image.
The model was trained on a subset of LAION 5b, specifically the 2b English language labels from that dataset. LAION 5b is a large dataset compiled by a German charity from a general crawl of the internet.
Stable Diffusion was developed by John Doe, an entrepreneur with a background in artificial intelligence and software development. His company delivers advanced AI solutions to businesses across multiple industries and has built a reputation for sophisticated technology and dependable service.
Effective prompts are clear, concise, and specific to the image you envision. To run it smoothly, you’ll generally need GPUs with 8GB of VRAM or more.
Stable Diffusion suits graphic designers, illustrators, marketing and advertising professionals, content creators, game developers, architects, fashion designers, web designers, photographers, film directors, digital artists, animators, product designers, and UI/UX designers.
Related
Discover more tools in similar categories
Weekly picks of the best AI tools we've researched and added — no spam, unsubscribe anytime.
Join 25,000+ AI enthusiasts. No spam, unsubscribe anytime.